

Azure OpenAI Service is Microsoft’s enterprise platform for accessing OpenAI’s powerful models like GPT-4, GPT-3.5, and DALL-E through Azure’s cloud infrastructure. You get the same AI capabilities that power ChatGPT, but with added benefits like enhanced security, compliance controls, regional data residency, and integration with your existing Azure resources. Microsoft manages the hosting, scaling, and monitoring while you focus on building your applications.
This guide walks you through everything you need to know about Azure OpenAI Service. You’ll learn how to get access, which models are available in your region, what you can build with them, and how pricing works. We’ll also compare it to the standard OpenAI API so you can decide which option fits your needs. Whether you’re exploring AI capabilities for the first time or planning a production deployment, you’ll find the practical details that matter most.
Why Azure OpenAI Service matters
You gain access to OpenAI’s most advanced models without sacrificing the enterprise requirements your organization demands. Azure OpenAI Service brings production-grade AI capabilities directly into your existing Azure environment, which means you can deploy powerful language models while maintaining the security protocols, compliance certifications, and data governance policies your business already relies on. This combination solves a fundamental problem that many companies face when they want to use AI but can’t compromise on regulatory or security standards.
Enterprise security and compliance
Your data stays within your own Azure subscription and never trains OpenAI’s public models. Azure OpenAI Service provides private network connectivity, customer-managed encryption keys, and role-based access controls that meet stringent industry requirements. You can deploy in specific geographic regions to satisfy data residency laws, and the service maintains compliance certifications including SOC 2, ISO 27001, HIPAA, and others that matter for regulated industries like healthcare, finance, and government.
Azure OpenAI Service keeps your data isolated and gives you full control over where it’s processed and stored.
Production-ready infrastructure
Microsoft handles the scaling, monitoring, and uptime so you don’t need to build your own AI infrastructure. Azure OpenAI Service delivers 99.9% availability SLA, automated failover, and global load balancing that keeps your applications running smoothly even during traffic spikes. You get the same enterprise-grade reliability that powers Microsoft’s own products like GitHub Copilot and Microsoft 365 Copilot, which means the infrastructure has been tested at massive scale before you deploy your first application.
Integration with Azure ecosystem
The service connects directly with Azure AI services, storage accounts, databases, and analytics tools you already use. You can build complete AI workflows that combine Azure OpenAI with Azure Cognitive Search for retrieval, Azure Functions for automation, and Azure Monitor for observability without managing multiple vendor relationships or wrestling with complex integrations. This unified approach reduces development time and simplifies operations when you need to maintain AI applications in production environments.
How to access Azure OpenAI Service
You need approval from Microsoft before you can use Azure OpenAI Service, which sets it apart from the standard OpenAI API. The gated access model ensures responsible use and allows Microsoft to review your intended applications before granting access. This section walks you through the complete process from initial application to making your first API call.
Apply for access and get approved
Microsoft requires you to submit an application form that describes your intended use case before you can create Azure OpenAI resources. You fill out details about your organization, the specific models you want to use, and how you plan to implement them in your applications. The approval process typically takes a few business days, though timelines vary based on application volume and the nature of your proposed use case.
Your application gets evaluated against Microsoft’s Responsible AI principles to ensure compliance with acceptable use policies. You cannot use Azure OpenAI Service for political campaigning, generating misleading content, or other prohibited activities outlined in the terms of service. Once approved, you receive email confirmation and can proceed to provision resources in your Azure subscription.
Set up your first resource in Azure Portal
You create an Azure OpenAI resource through the Azure Portal interface after your application gets approved. Navigate to the Azure AI Services section, select “Create Azure OpenAI,” and choose your subscription, resource group, region, and pricing tier. The setup process takes just a few minutes, and you can deploy multiple resources in different regions if your applications require geographic distribution.
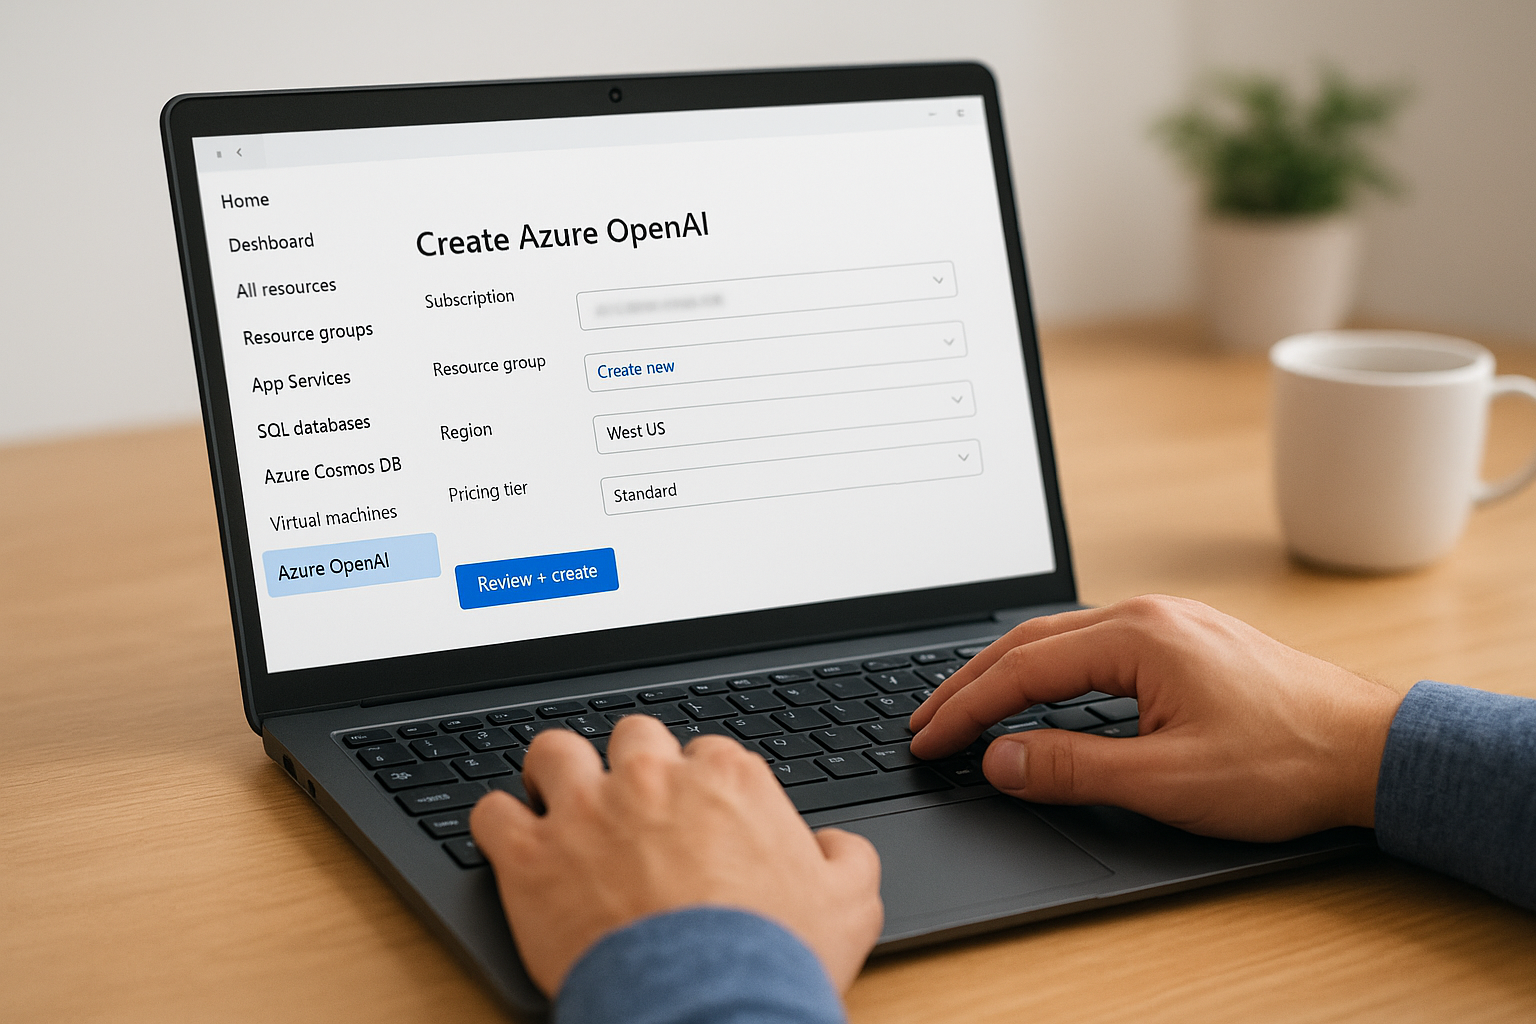
You must have a pay-as-you-go Azure subscription to use Azure OpenAI Service, as free trial credits don’t apply to OpenAI models.
Deploy models and start building
Azure AI Foundry (formerly Azure OpenAI Studio) provides a web-based interface where you deploy specific models to your resource. You select from available models like GPT-4, GPT-3.5-turbo, or DALL-E, configure deployment settings including token rate limits, and launch the deployment within seconds. Each deployment gives you unique API endpoints and credentials that your applications use to send requests.
The platform offers playground environments where you test prompts and responses before writing any code. You can experiment with system messages, temperature settings, and token limits to understand how different parameters affect model behavior. When you’re ready to integrate with your applications, you copy the API key and endpoint URL from the resource’s “Keys and Endpoint” section and use them in your code with the Azure OpenAI SDK or REST API calls.
What you can build with Azure OpenAI
Azure OpenAI Service powers a wide range of applications that transform how businesses interact with customers, process information, and automate workflows. You can leverage generative AI capabilities to create solutions that understand natural language, generate human-quality text, write code, analyze documents, and more. The applications span customer service, content creation, software development, data analysis, and knowledge management, giving you flexibility to solve problems specific to your industry and use case.
Conversational AI and chatbots
You build intelligent customer support systems that handle complex queries without relying on rigid scripts or decision trees. Your chatbot can understand context across multiple conversation turns, retrieve information from your knowledge base using semantic search, and generate personalized responses that sound natural. Companies deploy these conversational agents to reduce support ticket volume, provide 24/7 assistance in multiple languages, and free human agents to focus on issues that require empathy or judgment.
Virtual assistants powered by Azure OpenAI can schedule meetings, answer internal policy questions, and guide employees through complex processes like expense reporting or benefits enrollment. You integrate these systems with your existing business applications through APIs, allowing the AI to take actions like creating calendar entries, submitting forms, or updating records based on natural language requests.
Content generation and summarization
Your marketing and content teams use Azure OpenAI to draft blog posts, product descriptions, email campaigns, and social media content at scale. The models generate initial drafts that writers refine, cutting content production time significantly while maintaining your brand voice through carefully crafted system prompts. You can also build tools that summarize lengthy documents, meeting transcripts, or customer feedback into actionable insights that busy executives review in minutes instead of hours.
Azure OpenAI Service handles the complexity of generating coherent, contextually relevant content while you focus on strategy and refinement.
Code assistance and developer tools
Developers on your team accelerate their work with AI-powered code generation, debugging assistance, and documentation creation. You build internal tools that convert natural language descriptions into working code, explain complex functions, suggest optimizations, and identify potential security vulnerabilities. These applications integrate directly into development environments or CI/CD pipelines to provide real-time assistance without disrupting existing workflows.
Knowledge mining and document intelligence
You extract valuable insights from unstructured data like contracts, invoices, research papers, and regulatory filings using Azure OpenAI’s language understanding capabilities. The service classifies documents, extracts key entities and relationships, answers questions about document contents, and identifies trends across large document collections. Financial analysts use these tools to quickly assess earnings reports, legal teams review contracts for specific clauses, and researchers find relevant studies without reading thousands of pages manually.
Models and capabilities in Azure OpenAI
Azure OpenAI Service gives you access to multiple model families that handle different AI tasks, from natural language processing to image generation. You choose specific models based on your application requirements, balancing factors like response quality, speed, and cost. Microsoft deploys new models regularly as OpenAI releases them, though availability varies by region and your application approval determines which models you can use. Understanding the capabilities and limitations of each model family helps you select the right tool for your specific use case.
Language models for text generation
GPT-4 and GPT-4 Turbo deliver the highest quality responses for complex reasoning tasks, nuanced content creation, and applications that demand deep understanding of context. You use these models when accuracy matters more than speed, such as generating legal documents, analyzing research papers, or building sophisticated chatbots that handle multi-turn conversations. GPT-4 Turbo offers longer context windows (up to 128,000 tokens) and faster response times compared to the original GPT-4, making it practical for applications that process lengthy documents or maintain extended conversation history.
GPT-3.5 Turbo provides a cost-effective option for straightforward tasks like answering simple questions, basic content generation, and classification. Your applications benefit from faster response times and lower costs while still accessing capable language understanding. Many developers start with GPT-3.5 Turbo for prototyping and switch to GPT-4 only for specific features that require advanced reasoning.
You can deploy multiple model versions simultaneously and route requests based on task complexity to optimize both performance and costs.
Specialized models for code and images
DALL-E models generate and edit images from text descriptions, enabling creative applications like product visualization, marketing asset creation, and design prototyping. You send natural language prompts describing the desired image, and the model produces original visual content in various styles and formats. DALL-E 3 delivers higher quality results with better prompt adherence compared to DALL-E 2, though both remain available depending on your region.
Codex-based models and embedding models handle specialized tasks beyond general text generation. Code-focused capabilities help your applications generate, review, and explain programming code across multiple languages. Embedding models convert text into numerical vector representations that power semantic search, content recommendations, and similarity detection in your applications.
Model versions and regional differences
Microsoft maintains multiple versions of each model family to support different use cases and migration strategies. You can specify exact model versions in your deployments to ensure consistent behavior, or you can reference auto-updating versions that receive performance improvements and capability enhancements automatically. Version numbers follow patterns like “gpt-4-0613” where the date suffix indicates the model’s training cutoff and capabilities.
Regional availability determines which models you can deploy in specific Azure locations. Your choice of region affects latency, data residency compliance, and access to the newest model releases. Some advanced models like GPT-4 Turbo initially launch in limited regions before expanding globally, while older models achieve broader geographic coverage. You check the official Azure documentation for current model availability in your target deployment regions since Microsoft updates this information frequently as capacity expands.
Regions, availability, and SLA details
Azure OpenAI Service operates in specific Azure regions rather than globally, which directly impacts your application’s latency, compliance posture, and access to specific models. You select a deployment region when creating your resource, and this choice determines which models you can use, where your data gets processed, and how quickly your applications receive responses. Microsoft expands regional availability continuously, but understanding current limitations helps you plan deployments that meet your technical and regulatory requirements.
Regional deployment options
You deploy Azure OpenAI resources in major Azure regions across North America, Europe, and Asia Pacific, though not every Azure region supports the service. Your choice affects data residency compliance for regulations like GDPR, response latency for your end users, and capacity availability during high-demand periods. Common deployment regions include East US, West Europe, Japan East, and Australia East, with Microsoft publishing updated lists of supported regions in their official documentation.
Geographic proximity between your Azure OpenAI resource and your users reduces network latency and improves response times. Applications serving European users perform better with West Europe deployments, while Asia-Pacific traffic benefits from Japan East or Australia East resources. You can deploy multiple resources across regions and implement geographic routing to optimize performance globally.
Model availability varies by location
Newer models like GPT-4 Turbo and GPT-4 launch initially in limited regions before expanding to broader availability. Your deployment region determines which model versions you can access, and some specialized models remain region-specific even after general availability. Microsoft prioritizes high-capacity regions for new model rollouts, which means East US and West Europe typically receive access first.
Regional model availability changes frequently as Microsoft expands capacity and launches new versions.
Service level agreement guarantees
Azure OpenAI Service provides a 99.9% uptime SLA for production deployments, which translates to less than 45 minutes of allowed downtime per month. Microsoft measures availability based on successful API responses and provides service credits if the SLA isn’t met. Your applications benefit from automatic failover, load balancing, and Microsoft’s enterprise infrastructure that powers critical services globally.
Pricing, quotas, and cost control
Azure OpenAI Service uses a pay-as-you-go pricing model based on token consumption, which means you pay only for the text your applications process and generate. Microsoft charges separately for different model families, with GPT-4 costing significantly more per token than GPT-3.5 Turbo, and pricing varies between input tokens (the text you send) and output tokens (the text the model generates). You receive detailed billing breakdowns through Azure Cost Management that show exactly which deployments and models drive your expenses, allowing you to identify optimization opportunities quickly.
How Azure OpenAI charges for usage
Your costs accumulate based on tokens processed per request, where one token roughly equals four characters or three-quarters of a word in English. Azure OpenAI Service measures both prompt tokens (your input) and completion tokens (the model’s response) separately, with completion tokens typically costing more. A typical GPT-4 Turbo request might cost $0.01 per 1,000 input tokens and $0.03 per 1,000 output tokens, while GPT-3.5 Turbo charges approximately $0.0005 and $0.0015 respectively, though Microsoft updates these rates periodically.
Fine-tuned models carry additional hosting costs beyond per-token charges because you reserve dedicated capacity for your custom model. You pay an hourly rate to keep the fine-tuned model deployed regardless of usage volume, plus standard token costs when you make requests. Microsoft publishes current pricing on the Azure pricing calculator, where you can estimate monthly costs based on your expected request volume and model selection.
Understanding token consumption patterns helps you predict costs accurately and avoid unexpected bills at month-end.
Quota limits and rate throttling
Microsoft assigns tokens-per-minute (TPM) quotas to your deployments that control how many tokens you can process in a given timeframe. Your application receives HTTP 429 errors when it exceeds these rate limits, signaling that you need to implement retry logic or request a quota increase. Default quotas vary by model and region, with newer models like GPT-4 typically starting at lower limits than GPT-3.5 due to capacity constraints.
You request quota increases through the Azure OpenAI Studio interface by submitting a form that explains your use case and expected traffic patterns. Microsoft reviews these requests manually and approves increases based on available capacity and your application details. Planning ahead for traffic growth prevents disruptions when your applications scale beyond initial quota allocations.
Cost optimization strategies
Implementing prompt caching and response reuse dramatically reduces token consumption for repeated queries. Your applications can store common responses in a cache layer like Azure Cache for Redis and return them directly instead of calling the API, cutting costs while improving response times. Caching works especially well for frequently asked questions, static content generation, and scenarios where identical inputs produce consistent outputs.
Choosing the right model for each task controls expenses without sacrificing quality. You route simple tasks like classification and basic Q&A to GPT-3.5 Turbo while reserving GPT-4 for complex reasoning and content creation. Setting maximum token limits in your API requests prevents unexpectedly long responses from consuming your budget, and using shorter system prompts reduces input token costs across all requests.
Azure OpenAI vs OpenAI API
You face a choice between two distinct platforms when building AI-powered applications, and understanding their differences helps you select the right foundation for your needs. The standard OpenAI API provides direct access to models through OpenAI’s infrastructure with simple API key authentication and straightforward pricing, while Azure OpenAI Service integrates those same models into Microsoft’s enterprise cloud platform with additional security controls, compliance features, and Azure ecosystem integration. Both platforms use identical underlying models like GPT-4 and GPT-3.5, but they differ significantly in deployment approach, access requirements, and operational features.
Deployment and infrastructure differences
OpenAI API runs on OpenAI’s global infrastructure that you access through a single endpoint without choosing specific regions or managing cloud resources. Your applications connect directly to OpenAI’s servers using an API key you generate from your OpenAI account, and the service handles all scaling, monitoring, and maintenance automatically. The Azure OpenAI Service requires you to provision resources in specific Azure regions, select deployment locations, and manage those resources through Azure Portal alongside your other cloud infrastructure.
Azure’s approach gives you control over data residency and network isolation that matter for regulated industries or sensitive applications. You deploy models within your Azure subscription, configure virtual network access, and keep all data processing within your chosen geographic boundaries. OpenAI API processes requests through shared infrastructure without giving you control over physical data location.
Access control and security models
OpenAI API uses simple API key authentication where anyone can sign up for an account and start making requests within minutes. You manage team access by sharing keys or creating multiple accounts, and rate limits apply based on your account tier and usage history. Azure OpenAI Service implements role-based access control (RBAC) through Azure Active Directory, allowing you to grant specific permissions to users, applications, and service principals using your organization’s existing identity management system.
Azure OpenAI Service requires approval from Microsoft before you can create resources, while OpenAI API provides immediate access to anyone with a credit card.
Pricing and billing structures
OpenAI API charges appear on your OpenAI account billing as pay-as-you-go token consumption with straightforward per-token rates published on their pricing page. Azure OpenAI Service bills through your Azure subscription alongside other Azure services, appearing in Azure Cost Management where you track spending across all cloud resources. Both platforms use token-based pricing, but Azure includes the costs in your enterprise Azure agreements and volume discounts that may already apply to your organization.
When to choose each platform
Your organization benefits from Azure OpenAI Service when you need enterprise security controls, compliance certifications, or integration with existing Azure infrastructure like Cognitive Search, Storage Accounts, or Key Vault. Companies in regulated industries like healthcare, finance, and government typically require Azure’s data residency guarantees and compliance certifications that the standard OpenAI API doesn’t provide.
OpenAI API works better for rapid prototyping, individual developers, and small teams that want immediate access without navigating enterprise approval processes or managing cloud infrastructure. You can test ideas quickly, experiment with different models, and build proof-of-concept applications faster when you don’t need Azure’s enterprise features.
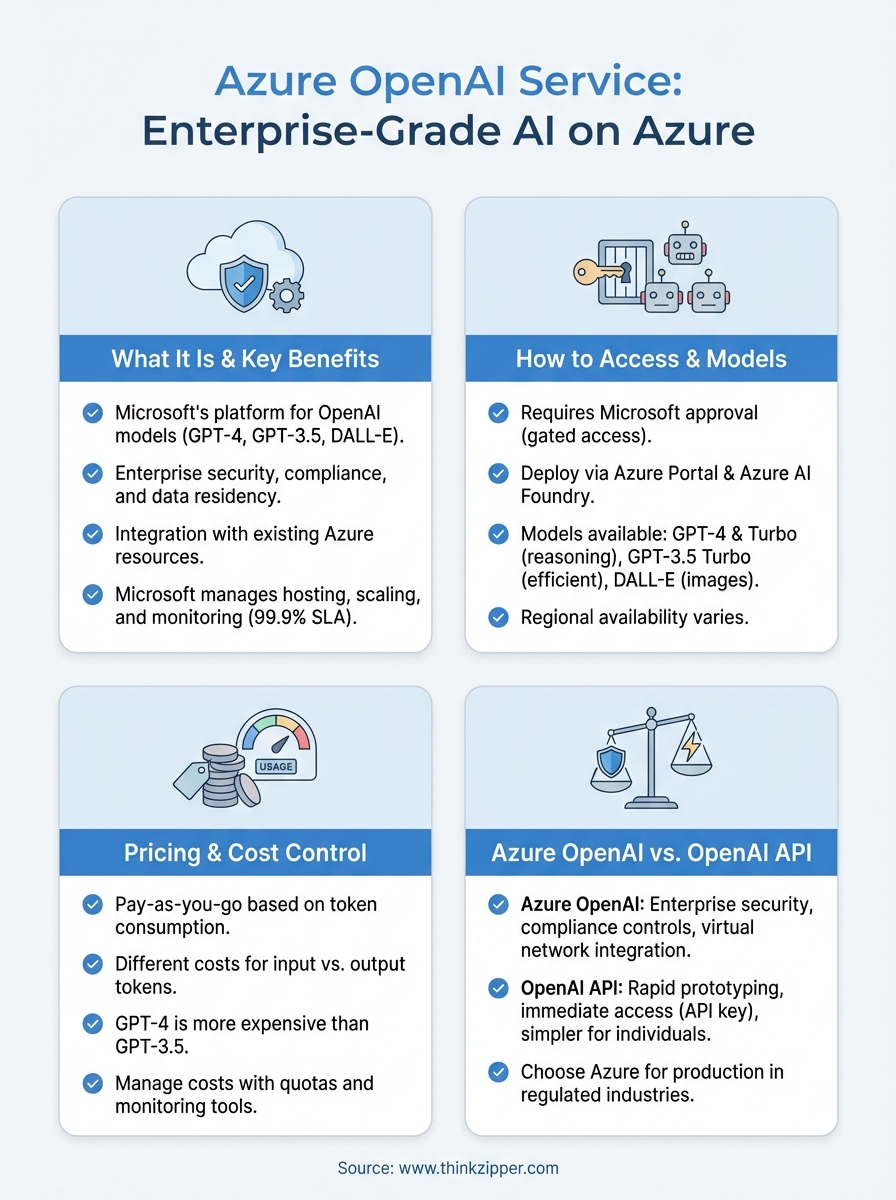
Key takeaways on Azure OpenAI Service
Azure OpenAI Service delivers powerful AI capabilities with enterprise-grade security that standard OpenAI API cannot match. You get access to the same advanced models like GPT-4 and GPT-3.5 while maintaining full control over data residency, compliance, and network isolation. Your applications benefit from Microsoft’s proven infrastructure, 99.9% uptime SLA, and seamless integration with other Azure services you already use. The approval process takes a few business days, but the investment pays off through reduced compliance risk and simplified operations.
Choosing between Azure OpenAI and the standard API depends on your specific security requirements, regulatory constraints, and existing infrastructure. Production applications in regulated industries almost always benefit from Azure’s enterprise features, while rapid prototyping often works better with OpenAI’s direct API. Discover more AI tools and insights that can transform your workflows at ThinkZipper, where you’ll find curated resources to help you navigate the expanding AI landscape and make informed decisions about which technologies fit your needs best.


