

A generative AI platform architecture defines how you organize models, data pipelines, orchestration tools, and infrastructure into a production-ready system. Think of it as your blueprint for building applications that generate text, images, or code at scale. You need more than just an LLM API call. You need retrieval systems, guardrails, monitoring, and governance working together. Without a clear architecture, your proof of concept will never survive real users.
This guide breaks down the core layers and components you need to build a generative AI platform that works in production. You’ll learn how to structure data flows, implement RAG patterns, add safety controls, and scale your infrastructure. We cover practical patterns from companies already running these systems, not theoretical concepts. Each section gives you specific decisions to make and tradeoffs to consider. By the end, you’ll have a reference blueprint you can adapt to your own projects.
Why generative AI platform architecture matters
You can prototype a generative AI application in hours with a few API calls, but production systems require serious architectural planning. Your demo might work for 10 users, but it will break under real load without proper infrastructure. Companies waste months rebuilding their entire stack because they skipped architectural decisions early. The difference between a successful AI platform and an expensive failure comes down to how you structure your components from day one.
Production challenges require architectural solutions
Your architecture determines whether you can handle concurrent users, maintain consistent responses, and control escalating costs. Without proper request routing and caching layers, your API bills will explode as traffic grows. You need to decide how to manage model versions, roll back bad deployments, and monitor performance across thousands of requests. Most teams discover these requirements only after their application starts crashing or costing thousands per day. A solid generative ai platform architecture prevents these problems by building the right abstractions before you scale.
Architectural decisions you make early become constraints you live with later, so plan for scale from the start.
Security and governance are not optional
Your platform needs built-in controls for data privacy, content filtering, and access management from the beginning. Adding guardrails after deployment means retrofitting security into every component you built. Regulated industries require audit trails, data lineage, and compliance checks at every layer. You cannot bolt these features onto a prototype architecture without major refactoring. Companies building in healthcare, finance, or legal domains must prove their platform follows strict governance standards before processing real user data. Architecture matters because it defines where you enforce policies, log decisions, and protect sensitive information throughout your entire system.
How to design a generative AI platform
You start designing your generative AI platform by defining your specific use cases and technical constraints rather than assembling every possible component. Different applications require different architectural layers. A simple chatbot needs far fewer components than a multi-agent system with external tool access. Your design process should work backwards from business requirements to technical components, not the other way around. Most teams overcomplicate their initial architecture by building infrastructure they will not use for months.
Start with your use case and constraints
Your use case determines which architectural patterns you actually need to implement. Customer support chatbots require conversation state management and knowledge retrieval, but they might not need complex multi-agent orchestration. Content generation tools need robust prompt templates and output validation, while code assistants require specialized model selection and execution environments. You should map your functional requirements to specific architectural components before writing any code. Understanding your constraints around latency, cost per request, data privacy, and scalability helps you eliminate unnecessary complexity from your initial design.
Design your architecture around the problems you have today, not the ones you might face next year.
Map components to maturity levels
Your organization’s AI maturity level dictates which components belong in your architecture right now. A level 1 system might only need prompt engineering and a model API, while level 3 requires full RAG implementation with vector databases. You waste engineering time building advanced features before mastering simpler patterns. Start with basic components that deliver immediate value, then add sophistication as your team gains experience and your use cases demand it. Companies often build complex orchestration frameworks when they still struggle with basic prompt consistency. Your generative ai platform architecture should evolve incrementally as you prove value at each stage.
Design for modularity and integration
Build your platform with independent, replaceable components rather than tightly coupled systems. Your retrieval layer should work regardless of which embedding model you choose. Orchestration logic should remain separate from your model serving infrastructure. This modularity lets you swap components without rewriting your entire application. Design clear interfaces between layers so you can upgrade your vector database or switch model providers without breaking dependent systems. Integration patterns matter more than individual tool choices because your requirements will change faster than you expect. Teams that build flexible architectures can adapt to new models and techniques without major refactoring.
Core layers of a generative AI platform
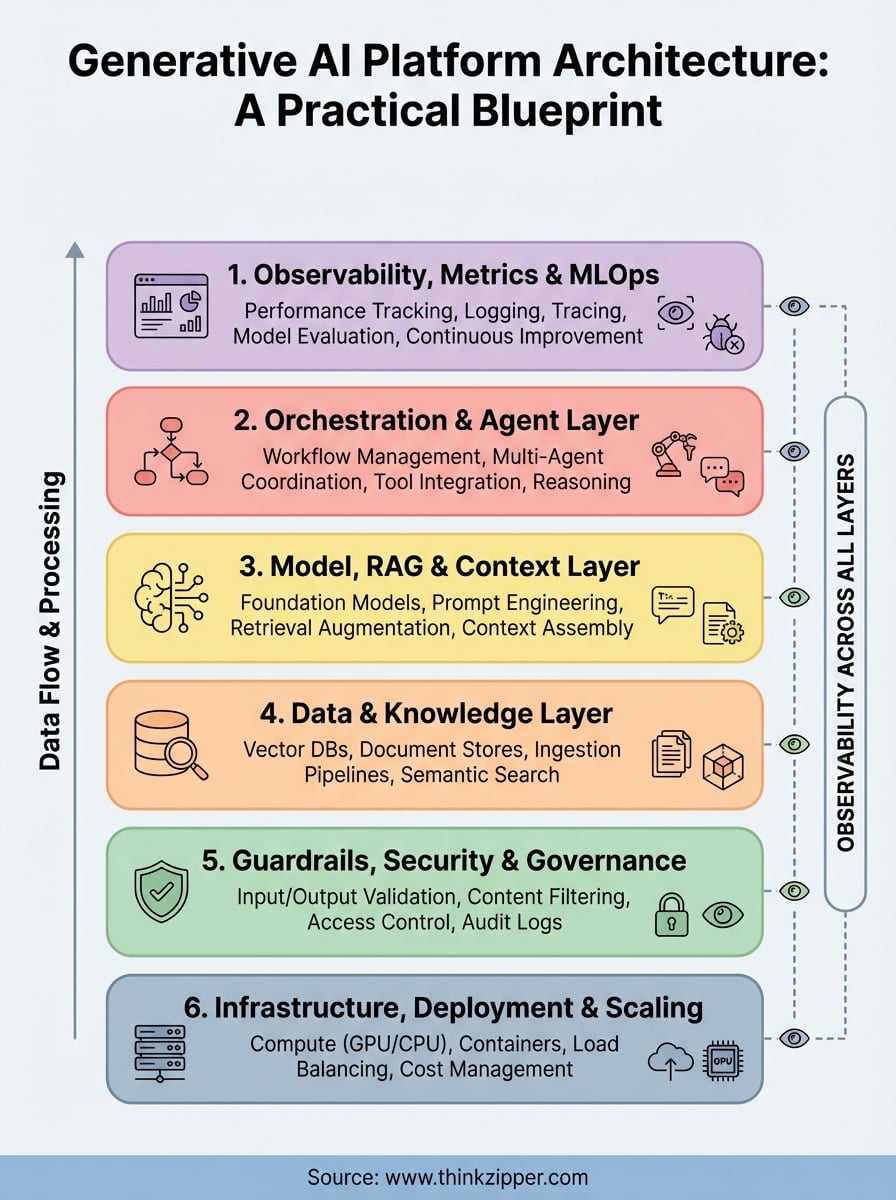
Your generative ai platform architecture organizes into distinct functional layers that work together to process requests, generate responses, and maintain system health. Each layer handles specific responsibilities, from storing knowledge to serving predictions to monitoring performance. You can visualize these layers as a vertical stack where data flows upward through transformation steps until your application delivers a final response. Understanding how these layers interact helps you make better decisions about where to invest engineering effort and which components to prioritize. Teams that skip layers or merge responsibilities into single components create brittle systems that break under production load.
The six foundational layers
Most production platforms implement six core layers that separate concerns and enable independent scaling. Your data and knowledge layer manages all information sources including vector databases, document stores, and structured data systems. The model and RAG layer handles language model selection, prompt engineering, retrieval augmentation, and context construction. Your orchestration and agent layer coordinates workflows, manages multi-step reasoning, and handles tool integration. The guardrails and governance layer enforces safety policies, content filtering, and compliance requirements across every request. Your infrastructure layer provisions compute resources, manages deployments, and handles scaling decisions. Finally, the observability layer tracks metrics, logs events, and enables debugging throughout the entire system.
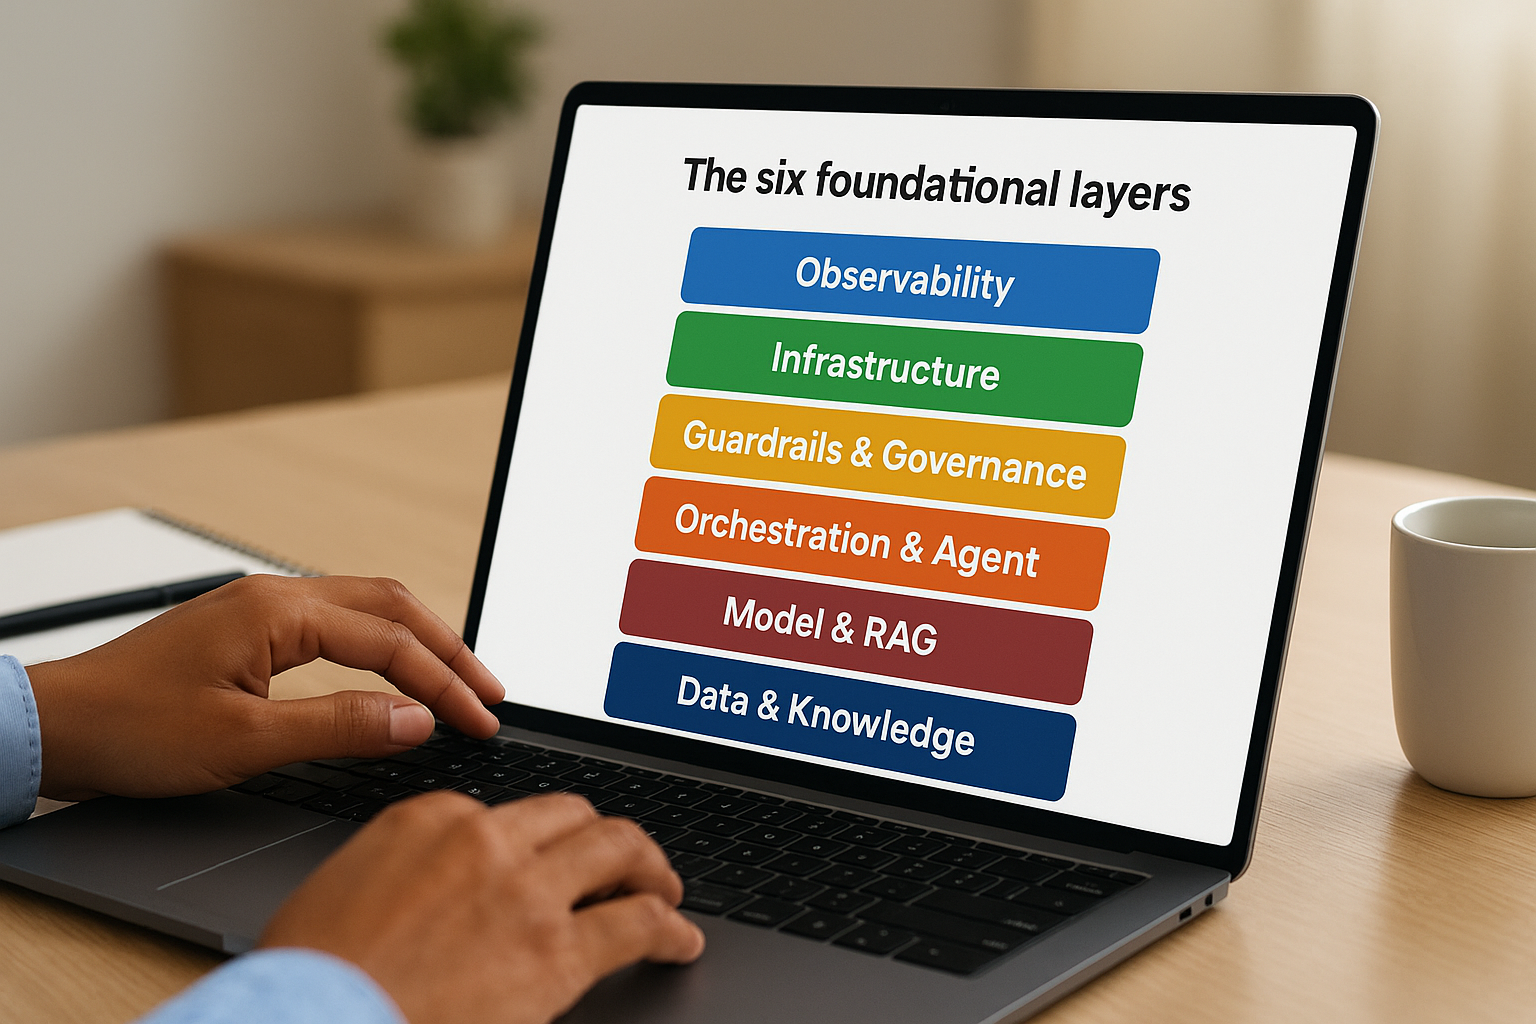
You need all six layers working together before your platform can handle real production traffic at scale.
How layers communicate and depend on each other
Each layer consumes outputs from lower layers and provides inputs to higher ones in a clear dependency chain. Your orchestration layer cannot function without models from your model layer and data from your knowledge layer. Guardrails inspect outputs at multiple points, checking both retrieved context and generated responses before they reach users. Your infrastructure layer supports everything above it, providing the compute, storage, and networking that other layers require. Observability cuts across all layers, collecting signals from each component to build a complete picture of system behavior. Teams that blur these boundaries create circular dependencies that make debugging and scaling nearly impossible.
Deciding which layers belong in your architecture
You do not need to implement every layer with equal sophistication from day one. Your maturity level and use case determine which layers require the most investment initially. A basic chatbot might need simple prompt engineering and model serving but can skip advanced orchestration entirely. Content moderation applications demand robust guardrails but might use simpler data pipelines than systems requiring complex RAG implementations. Start by building the minimum layers that support your core use case, then add sophistication as requirements grow. Companies waste months building comprehensive observability frameworks when they still struggle with basic retrieval accuracy. Your layer implementation should match the complexity your application actually needs today, not what you think you might need eventually.
Data and knowledge layer
Your data and knowledge layer serves as the foundation for all information your generative AI platform accesses during request processing. This layer manages everything from raw document ingestion to vector embeddings that enable semantic search. You cannot build effective retrieval systems without properly organizing how your platform stores, indexes, and retrieves knowledge. Most teams underestimate the complexity of this layer until they face production issues with inconsistent retrieval quality or slow query performance. Your architecture decisions here directly impact the accuracy and relevance of every response your system generates.
Organizing your data sources
You need to support multiple data formats and storage systems within your knowledge layer since enterprise information exists in various forms. Your platform should handle unstructured data like PDFs, Word documents, and web pages alongside structured data from databases and spreadsheets. Document management systems require different processing pipelines than real-time API data sources. Teams often make the mistake of forcing all data through a single pipeline, which creates bottlenecks and limits flexibility. Design your ingestion layer to accept diverse sources while normalizing them into consistent formats downstream.
Data freshness requirements vary dramatically across different knowledge sources. Your customer support knowledge base might need hourly updates while your product documentation updates weekly. Building separate pipelines with different refresh schedules prevents you from wasting compute resources on unnecessary reindexing. You should implement incremental updates rather than full reloads whenever possible to minimize processing costs and maintain system availability during updates.
Document processing and chunking strategies
Your documents need to be split into manageable chunks before they can be effectively retrieved and used as context for your models. Chunk size directly impacts both retrieval accuracy and the quality of generated responses. Smaller chunks provide more precise retrieval but might lack sufficient context, while larger chunks include more information but reduce retrieval precision. Most production systems use chunks between 200 and 800 tokens, though your optimal size depends on your specific use case and model context limits.
Choose chunking strategies that preserve semantic meaning rather than splitting documents at arbitrary character counts.
Overlap between chunks helps maintain context across boundaries where important information might otherwise get split. Implementing 10-20% overlap ensures your retrieval system can find relevant passages even when key terms appear near chunk edges.
Vector databases and embedding models
Vector databases enable semantic search by storing numerical representations of your text chunks that capture meaning rather than just matching keywords. Your choice of embedding model determines how well your system understands relationships between different pieces of content. You can use models from Google’s Vertex AI or other providers, but consistency matters more than specific model selection. Switching embedding models later requires reprocessing your entire knowledge base, so choose carefully upfront based on your language requirements and domain specificity.
Performance characteristics of your vector database affect query latency and scaling costs across your entire generative ai platform architecture. You need to balance approximate nearest neighbor search accuracy against query speed as your knowledge base grows. Some systems prioritize recall over speed while others optimize for sub-100ms queries at the cost of retrieving slightly less relevant results.
Model, RAG, and context layer
Your model and RAG layer transforms raw queries and retrieved knowledge into structured prompts that foundation models can process effectively. This layer sits between your data sources and your orchestration logic, handling the critical work of context assembly and generation. You need to decide which models to use, how to augment prompts with relevant information, and how to manage the token budgets that constrain every request. Teams that treat this layer as simple API calls discover serious problems when they face inconsistent outputs, context length violations, or unacceptable latency under load. Your generative ai platform architecture depends on getting these components right before adding complexity above or below this layer.
Selecting and serving foundation models
You choose foundation models based on task requirements, cost constraints, and latency targets rather than just picking the newest or most powerful option. Your customer support chatbot might perform perfectly with a smaller, faster model while your code generation system requires larger models with specialized training. Model selection directly impacts your infrastructure costs since more capable models typically charge higher rates per token and require more compute resources. You should evaluate models across multiple dimensions including response quality, speed, context window size, and cost per million tokens before committing to a provider.
Self-hosting models gives you complete control over data privacy and costs at the expense of managing inference infrastructure yourself. Using API-based models from providers like Google’s Vertex AI eliminates infrastructure management but means sending your data to external services. Most enterprises start with API-based models to validate use cases quickly, then evaluate self-hosting only after proving consistent value and reaching sufficient scale to justify the operational overhead.
Implementing retrieval augmented generation
RAG patterns prevent your models from hallucinating facts by grounding responses in retrieved documents from your knowledge layer. Your retrieval component fetches relevant chunks based on semantic similarity to the user query, then your context builder assembles these chunks into a coherent prompt structure. Basic RAG implementations simply concatenate top retrieved documents with your query template, while advanced systems implement multi-stage retrieval with reranking and query rewriting. You need to tune your retrieval count carefully since fetching too few documents reduces answer quality while too many waste tokens and increase latency.
Retrieval quality matters more than model size because even the best models cannot fix bad context.
Hybrid search strategies combine keyword-based retrieval with semantic search to improve precision across different query types. Your reranking stage uses faster, specialized models to score retrieved candidates and select the most relevant subset before final generation. This two-stage approach lets you retrieve broadly then filter precisely without overwhelming your generation model with irrelevant context.
Context construction and prompt templates
Your context builder assembles retrieved documents, system instructions, and user queries into structured prompts that fit within model token limits. Effective templates include clear role definitions, formatting instructions, and examples that guide model behavior consistently across requests. You should implement dynamic token management that adjusts retrieved content based on remaining capacity rather than using fixed chunk counts. Production systems track token usage per request component so you can identify which elements consume budget and optimize accordingly.
Template versioning enables you to test prompt improvements without breaking existing applications by routing specific user segments to new templates while maintaining stable defaults. Your prompt engineering work happens at this layer, separate from orchestration logic, so you can iterate on instruction quality without touching workflow code.
Orchestration and agent layer
Your orchestration layer coordinates multiple components and workflows across your generative ai platform architecture to transform simple requests into complex, multi-step operations. This layer decides which models to call, when to retrieve additional information, and how to combine outputs from different services into coherent responses. You need orchestration when your application requires more than a single model call to complete a task, such as when you must verify retrieved context, perform calculations, or access external APIs before generating a final answer. Teams building advanced AI applications discover that orchestration logic quickly becomes their most complex codebase if they do not structure it properly from the start.
Managing workflows and execution flow
Your workflow manager defines the sequence of operations that transform user inputs into final outputs across your platform. Simple workflows follow linear paths where each step feeds directly into the next, while complex workflows implement conditional branching based on intermediate results. You should design workflows as declarative configurations rather than hardcoded logic so you can modify execution patterns without rewriting application code. Production systems track execution state at each workflow step to enable retries, debugging, and performance analysis across thousands of concurrent requests.
Conditional logic in your workflows lets you route requests to different model configurations based on query characteristics detected earlier in the pipeline. Your orchestrator might send technical questions to specialized models while routing general queries to faster, cheaper options. This routing intelligence belongs in your orchestration layer rather than scattered across individual components because you need centralized visibility into decision-making logic as your system grows more sophisticated.
Implementing multi-agent patterns
Multi-agent systems coordinate specialized AI agents that each handle specific subtasks within a larger workflow. Your research agent might gather information while your synthesis agent organizes findings and your writing agent produces final content. Agent collaboration patterns range from simple sequential chains where each agent processes the previous agent’s output, to complex networks where agents negotiate and iterate toward solutions together. You need clear protocols for how agents communicate, share context, and signal completion to prevent infinite loops or conflicting outputs.
Agent-based architectures let you combine specialized capabilities that would be impossible to achieve with a single monolithic model.
Integrating external tools and functions
Your orchestration layer manages function calling and tool integration that extend model capabilities beyond text generation. Models can invoke calculators, search engines, database queries, or API calls when they recognize tasks requiring external actions. You define available tools through structured schemas that describe their inputs, outputs, and usage constraints so models understand when and how to invoke each function. Function execution happens outside your model layer, with your orchestrator handling the request-response cycle and feeding results back into the generation context for the next reasoning step.
Tool integration requires error handling and timeout management since external services introduce new failure modes into your system. Your orchestrator must decide whether to retry failed tool calls, fall back to alternative approaches, or return partial results when external dependencies become unavailable.
Guardrails, security, and governance
Your generative ai platform architecture requires comprehensive safety controls that protect both your users and your organization from AI-related risks at every layer of your system. Guardrails act as checkpoints that validate inputs, filter outputs, and enforce policies before content reaches end users or triggers automated actions. You cannot treat these controls as optional features you add later because security vulnerabilities and compliance failures create existential risks for production AI platforms. Companies that skip this layer during initial development spend months retrofitting controls across their entire codebase when auditors or incidents force them to address gaps. Building guardrails into your architecture from the beginning costs far less than fixing security problems after deployment.
Input validation and content filtering
Your input guardrails prevent malicious prompts and sensitive data from entering your processing pipeline where they could compromise your system or leak through to external model APIs. You need to scan every user query for personally identifiable information, proprietary data, and prompt injection attempts before sending anything to your model layer. Automated detection tools identify patterns like credit card numbers, social security numbers, and internal document references that should never leave your organization. Teams working in regulated industries must prove they filter sensitive data at ingestion rather than hoping their models avoid repeating it in responses.
Jailbreak detection requires pattern matching and anomaly detection that catches users trying to manipulate your models into generating harmful content or bypassing your intended constraints. Your filtering layer should block queries containing predefined phrases associated with policy violations while flagging unusual input patterns for human review. Implementing rate limiting and user authentication at this stage prevents abuse before it consumes expensive compute resources downstream.
Output guardrails and quality controls
Your output validation layer inspects every generated response for toxicity, factual inconsistencies, and policy violations before delivery to users. You should implement multiple checks including format validation for structured outputs, toxicity detection for harmful content, and hallucination detection for factually incorrect claims. Automated scoring models evaluate response quality across dimensions you define as critical for your application, from tone and professionalism to accuracy and completeness. Production systems often run multiple validation checks in parallel to minimize latency while maintaining comprehensive coverage.
Your guardrails must operate fast enough to remain invisible to users while blocking every response that violates your policies.
Fallback policies define what happens when outputs fail validation rather than just blocking bad responses. Your system might retry generation with modified prompts, route failed requests to human operators, or return curated safe responses that acknowledge limitations. Implementing smart retry logic with exponential backoff prevents infinite loops while giving your models multiple chances to produce acceptable outputs within your latency budget.
Access control and data privacy
Your governance layer enforces role-based permissions and audit logging across every component that processes user data or generates AI outputs. You need granular access controls that specify which users, applications, and services can invoke specific models, access particular data sources, or execute sensitive actions. Audit trails capture every request with enough detail to reconstruct decision paths during compliance reviews or security investigations. Teams building platforms for enterprises must demonstrate their systems maintain complete lineage from user queries through retrieval and generation to final responses.
Data residency requirements force you to control where information flows throughout your platform architecture. Your governance controls must prevent regulated data from crossing geographic boundaries or entering systems that lack appropriate compliance certifications.
Infrastructure, deployment, and scaling
Your infrastructure layer provides the compute, storage, and networking resources that enable your generative ai platform architecture to process requests reliably at scale. This layer handles everything from GPU provisioning for model inference to container orchestration for deploying multiple services across your platform. You need to make critical decisions about whether to build on cloud infrastructure, use managed services, or maintain on-premises deployments based on your cost structure, latency requirements, and data sovereignty constraints. Teams that underestimate infrastructure complexity discover their proof-of-concept architecture cannot handle production traffic volumes or maintain acceptable response times under load. Your deployment and scaling strategies determine whether your platform succeeds or collapses when real users start relying on your AI capabilities.
Compute resource management
Your model inference workloads require GPU acceleration for acceptable latency on most foundation models, though smaller models can run efficiently on CPU instances. You need to decide between dedicated GPU instances that maintain consistent performance versus shared resources that reduce costs but introduce variable latency. Auto-scaling policies should monitor queue depths and request latency rather than simple CPU metrics since AI workloads exhibit different scaling patterns than traditional applications. Production systems implement instance warm-up strategies that pre-load models into memory before routing traffic to new compute nodes, preventing cold start delays that frustrate users.
Cost optimization requires mixing instance types across your infrastructure to match workload characteristics with appropriate resources. Your retrieval and orchestration logic runs efficiently on standard CPU instances while your generation endpoints need GPU acceleration. Implementing spot instances or preemptible VMs for batch processing workloads can reduce costs by 60-80% compared to on-demand pricing, though you must design your system to handle interruptions gracefully.
Container orchestration and deployment patterns
Container platforms like Kubernetes provide standardized deployment and management for the diverse services comprising your AI platform. You package each component as a container image with explicit dependencies, enabling consistent deployments across development and production environments. Service mesh patterns handle traffic routing, load balancing, and failure recovery across your microservices without requiring custom logic in each component. Teams building complex platforms discover that container orchestration eliminates entire classes of deployment problems that plague traditional infrastructure approaches.
Blue-green deployments let you test new model versions in production without risking your stable traffic by maintaining parallel environments and switching routing atomically. Your deployment pipeline should automate validation steps that compare new model outputs against established baselines before promoting releases to full production traffic.
Scaling strategies for production load
Horizontal scaling adds more inference instances behind your load balancer to distribute request volume across additional compute capacity as traffic grows. Your platform should scale individual components independently rather than treating your entire stack as a monolithic unit that scales together. Load balancing algorithms must account for GPU memory warming and model loading times when routing requests to ensure even distribution across your inference fleet.
Your scaling decisions determine whether your platform costs grow linearly with usage or explode exponentially under production load.
Caching strategies reduce infrastructure requirements by storing frequently accessed results at multiple layers throughout your system. Request-level caching prevents redundant model calls for identical queries while context caching reduces token processing costs for repeated prompt segments.
Observability, metrics, and MLOps
Your observability layer provides visibility into every component of your generative ai platform architecture from request ingestion through final response delivery. This layer collects metrics, logs, and traces that let you understand system behavior, diagnose failures, and optimize performance across your entire platform. You cannot effectively operate AI systems without comprehensive observability because generative models exhibit unpredictable behaviors that traditional monitoring approaches fail to capture. Production teams spend more time debugging AI-specific issues like context truncation, retrieval failures, and output quality degradation than managing infrastructure problems. Your MLOps practices determine whether you can continuously improve your platform or repeatedly deploy changes that break existing capabilities.
Tracking model performance and quality metrics
You need to measure both technical performance and output quality across every request your platform processes. System metrics include time to first token, tokens per second, total latency, and throughput under various load conditions. Your monitoring dashboard should track these metrics per model, per user segment, and per request type so you can identify performance regressions before they impact user experience. Cost metrics capture token consumption by input and output separately, letting you optimize prompt engineering and context construction to reduce bills without sacrificing quality.
Quality metrics require domain-specific evaluation approaches that assess whether generated responses actually solve user problems correctly. You should track hallucination rates, factual accuracy, response relevance, and toxicity scores using automated evaluation models that score every production output. Teams building customer-facing applications implement user feedback loops that collect explicit ratings and implicit signals like conversation abandonment rates to complement automated metrics. Length-related metrics reveal patterns like verbose responses that waste tokens or truncated outputs that indicate context overflow problems.
Logging, tracing, and debugging
Your logging infrastructure captures complete request contexts including user queries, retrieved documents, and generated outputs to enable post-mortem analysis of failures and quality issues. Structured logs with consistent schemas let you query across millions of requests to identify patterns causing specific failure modes. Distributed tracing connects operations across your orchestration, retrieval, and generation layers so you can reconstruct the exact sequence of events that produced any particular response. Production systems implement trace sampling that captures detailed execution paths for representative requests without overwhelming storage systems.
Your traces must preserve enough context to reproduce any production issue in your development environment for effective debugging.
Real-time log analysis powered by anomaly detection algorithms alerts your team when request patterns, error rates, or latency distributions deviate from established baselines. You should aggregate logs from all platform components into centralized systems that support full-text search and time-series analysis rather than forcing engineers to SSH into individual instances during incidents.
MLOps practices for continuous improvement
Your MLOps pipeline automates model evaluation, deployment, and rollback processes that traditional CI/CD systems cannot handle effectively. You need specialized workflows that compare new model versions against established quality baselines using held-out test sets before promoting releases to production traffic. A/B testing frameworks route percentages of live traffic to competing model versions while tracking quality metrics and user satisfaction to determine which implementation performs better. Teams building sophisticated platforms implement shadow deployments that process production requests with candidate models without affecting user-facing responses, building confidence in new versions before risking real traffic.
Model drift detection monitors prediction quality over time to catch when your platform’s performance degrades due to changing user behaviors or data distributions. Your MLOps system should trigger retraining workflows automatically when drift metrics exceed acceptable thresholds rather than waiting for users to complain about declining quality.
Common patterns and reference blueprints
Your generative ai platform architecture benefits from established patterns and reference designs that others have validated in production environments. These blueprints provide starting points that help you avoid common mistakes while adapting proven structures to your specific requirements. You should study multiple reference architectures before committing to your own design since different patterns optimize for different priorities like cost, latency, or flexibility. Teams that start from scratch often recreate problems that established patterns already solve, wasting months building components that could have been structured better from the beginning.
Three-tier pattern for basic implementations
The three-tier pattern separates your platform into presentation, logic, and data layers that operate independently while communicating through defined interfaces. Your presentation tier handles user interactions and displays outputs, your logic tier orchestrates models and workflows, and your data tier manages knowledge bases and vector storage. This pattern works well for straightforward applications like chatbots or document question-answering systems where you need clear separation of concerns without complex agent coordination. Companies building their first production AI platform often adopt this pattern because it maps naturally to existing web application architectures their teams already understand.
Start with simpler patterns that match your current capabilities before adopting complex multi-agent or event-driven architectures.
Event-driven architecture for asynchronous processing
Event-driven patterns use message queues and event buses to decouple components that process requests asynchronously across your platform. Your system publishes events when users submit queries, when retrieval completes, or when generation finishes, allowing multiple consumers to react independently. This approach enables horizontal scaling and fault tolerance since failed components can retry processing without blocking upstream services. Production platforms handling high volumes or long-running workflows benefit from event-driven designs that prevent request timeouts and enable partial result delivery while background tasks continue processing.
Reference blueprint from cloud providers
Major cloud providers publish complete reference architectures that integrate their managed services into working AI platforms. These blueprints typically include infrastructure-as-code templates, service configurations, and deployment pipelines you can customize for your needs. Your team saves weeks of integration work by starting from proven blueprints rather than assembling components yourself, though you trade some flexibility for faster implementation. Reference designs from providers like Google Cloud demonstrate how to connect vector databases, model endpoints, orchestration services, and monitoring tools into cohesive systems that handle production traffic reliably.
Final thoughts
Your generative ai platform architecture determines whether your AI application succeeds or fails in production. Building the right foundation with proper layers for data, models, orchestration, guardrails, and infrastructure prevents the expensive refactoring that teams face when they scale proof-of-concepts without architectural planning. You need to match your component selection and sophistication to your actual maturity level and use case rather than implementing every possible feature from day one. Start with the core layers your application requires today, then expand systematically as you prove value and face new requirements.
Production-ready platforms require careful attention to security, governance, and observability alongside your technical components. Teams that skip these concerns during initial development waste months retrofitting controls and monitoring into systems built without them. Your architecture should evolve incrementally as your needs grow, but the fundamental patterns and layer separation you establish early will constrain or enable everything you build later. Explore more AI tools and insights to discover solutions that can enhance your platform’s capabilities across every layer of your architecture.


