

Google Vertex AI generative AI is a platform that lets you build, deploy, and manage AI applications powered by large language models. It brings together Google’s Gemini models, third party options, and enterprise tools into one environment. You get access to pretrained models, prompt engineering interfaces, and the infrastructure to run generative AI at scale. Instead of piecing together different services and APIs, you work inside a unified system designed for production grade applications.
This guide walks you through everything you need to know about using Vertex AI for generative projects. You’ll learn why enterprises choose this platform over alternatives, how to get started with your first model, what’s available in the Model Garden, and how to use Vertex AI Studio for quick prototyping. We’ll also cover prompt design techniques and model tuning strategies that help you get better results from your AI applications.
Why Vertex AI stands out for generative projects
You face a crowded market of AI platforms, but Vertex AI distinguishes itself through integration depth and enterprise readiness. The platform gives you direct access to Google’s infrastructure that powers services like Gmail and Search, which means you’re building on systems proven at massive scale. Unlike standalone API services that limit you to basic model calls, google vertex ai generative ai combines model access with full development, deployment, and monitoring capabilities in one environment.
Enterprise-grade infrastructure and security
Your generative AI applications run on the same infrastructure Google uses internally, which handles billions of requests daily. You get automatic scaling that adjusts to demand without manual intervention, and you pay only for what you consume. The platform includes VPC Service Controls that let you define security perimeters around your data, keeping sensitive information within your organization’s boundaries. Your models and data stay in regions you specify, meeting compliance requirements for industries like healthcare and finance.
Data governance tools give you granular control over access permissions at every level. You can track who accesses which models, audit all API calls, and set up approval workflows for production deployments. These features matter when you’re processing customer data or proprietary business information through AI systems.
Unified access to multiple AI models
The Model Garden removes the complexity of managing different model providers and APIs. You access Gemini models, open source options like Llama, and specialized models through a single interface with consistent authentication and billing. This eliminates the need to maintain separate accounts and integrations for each model provider you want to test.
When you need to compare model performance on your specific use case, you can run the same prompt through multiple models without changing your code structure.
You can switch between models by updating a single parameter in your API call. This flexibility lets you optimize for cost, speed, or quality depending on each task’s requirements. A customer service chatbot might use a lighter model for simple questions while routing complex queries to more capable models.
Built-in MLOps and deployment tools
Vertex AI handles the operational complexity that typically slows down AI projects. You get automated model versioning that tracks every change to your prompts, parameters, and fine-tuning data. The platform monitors model performance in production and alerts you when outputs drift from expected patterns. You can roll back to previous versions instantly if a new deployment causes issues.
Pipeline orchestration tools let you automate the entire workflow from data preparation through model training to deployment. You define each step once, then the platform executes them in sequence whenever you trigger the pipeline. This consistency reduces errors and makes your AI applications more reliable. Integration with BigQuery means you can process training data at scale without moving it between systems, saving time and reducing security risks.
How to start building with Vertex AI
You can launch your first google vertex ai generative ai project in minutes once you understand the basic setup process. The platform requires a Google Cloud account and an active project with billing enabled, but you don’t need deep machine learning expertise to begin experimenting. Your initial steps focus on accessing the console, enabling the necessary APIs, and running a simple model query to verify everything works correctly.
Setting up your Google Cloud project
You start by creating or selecting a Google Cloud project in the Cloud Console, which serves as the container for all your Vertex AI resources. Navigate to the Vertex AI section and enable the Vertex AI API for your project, which typically takes less than a minute. The console prompts you to set up billing if you haven’t already, and Google provides $300 in free credits for new users to test services without immediate cost concerns.

Your project needs appropriate IAM permissions to access generative AI features. You assign yourself or your team members the Vertex AI User role at minimum, which grants permission to call models and use Studio features. Organizations with stricter security requirements can create custom roles that limit access to specific models or geographic regions.
Making your first API call
The quickest way to test your setup involves using Vertex AI Studio through the web interface rather than writing code immediately. You open Studio from the Vertex AI menu, select a model like Gemini 1.5 Pro, and type a prompt directly into the interface. The platform returns a response within seconds, confirming your authentication and billing configuration work correctly.
Once you verify the web interface functions properly, you can transition to programmatic access using the Python SDK or REST API.
Your code-based approach requires installing the Google Cloud SDK and authenticating with your project credentials. A basic Python script needs just a few lines to import the necessary libraries, initialize the client with your project ID, and send a prompt to a model. You receive structured JSON responses that include the generated text, token usage statistics, and safety attribute scores that help you monitor output quality.
Exploring models in the Vertex AI Model Garden
The Model Garden functions as your central hub for discovering and deploying AI models within google vertex ai generative ai. You browse through hundreds of pretrained models organized by capability, provider, and use case rather than hunting across different platforms. Each model listing displays performance benchmarks, pricing information, and recommended applications, which helps you make informed choices without extensive testing. Your access extends beyond Google’s own models to include open source options and third party offerings, all available through the same authentication and deployment workflow.
Understanding Gemini model options
You find multiple Gemini variants designed for different performance and cost requirements in your applications. Gemini 1.5 Pro handles complex reasoning tasks and processes long context windows up to one million tokens, making it suitable for analyzing entire codebases or lengthy documents. Gemini 1.5 Flash delivers faster responses at lower cost when you need quick interactions for chatbots or real-time applications.
The multimodal capabilities of Gemini models let you process text, images, audio, and video within a single request. You can ask questions about uploaded images, extract information from PDF documents, or generate descriptions of video content without preprocessing files into different formats. This flexibility reduces the number of specialized models you need to maintain.
Your choice between Gemini versions depends on whether you prioritize response quality or processing speed for each specific task.
Working with open source and third-party models
Open source models like Llama and Mistral give you alternatives when you need specific capabilities or want to avoid vendor lock-in. You deploy these models through the same interface you use for Gemini, but you gain additional flexibility to fine-tune parameters and customize behavior for specialized domains. The platform handles infrastructure provisioning automatically regardless of which model you select.
Third-party commercial models from providers like Anthropic appear alongside Google’s offerings when they expand the range of available capabilities. You compare pricing and performance across providers without managing separate billing relationships or API integrations. Model Garden updates regularly with new options, so you check back periodically to discover recently added models that might better serve your requirements.
Using Vertex AI Studio for rapid prototyping
You accelerate your development timeline significantly by using Vertex AI Studio as your experimentation environment before writing production code. The browser-based interface removes setup friction that typically slows early stage testing, letting you evaluate different models and adjust parameters instantly without deploying infrastructure. Your team members can collaborate on prompt development through shared workspaces, which helps establish consistent approaches across projects. Studio saves every interaction automatically, creating a history you reference when comparing outputs from different configuration attempts.
Testing prompts without writing code
Studio’s freeform text interface lets you type prompts and receive model responses within seconds of opening the platform. You select your preferred model from a dropdown menu, adjust temperature and token limits through sliders, and view results immediately alongside your input. The platform displays token consumption and response time metrics for each request, helping you estimate production costs before committing to a specific approach.
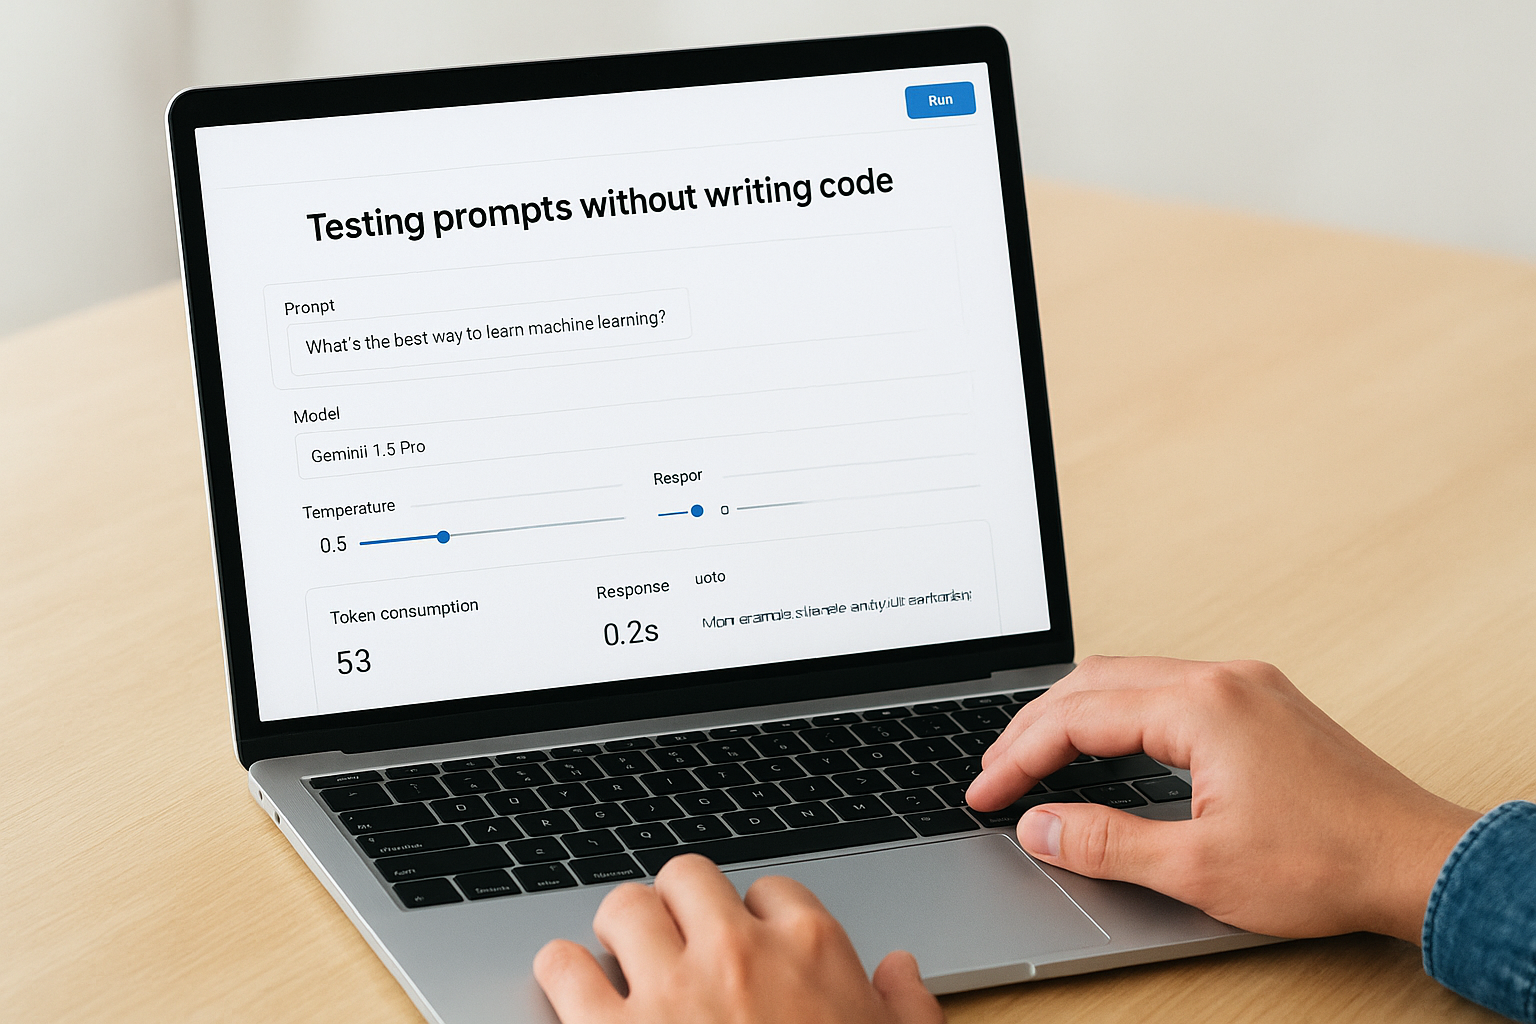
Your ability to test variations quickly means you discover optimal prompt structures in hours rather than days of code-based experimentation.
Safety filters activate automatically and flag potentially problematic outputs, giving you early visibility into content moderation requirements. You can switch between models mid-session to compare how Gemini 1.5 Pro and Gemini 1.5 Flash handle identical prompts, identifying which version delivers acceptable quality at lower cost for your use case.
Iterating on responses in real time
Real-time feedback loops in Studio help you refine prompts based on actual model behavior rather than assumptions. You modify a single word in your instruction, resubmit the request, and observe how the change affects output structure or accuracy. Multimodal testing works through simple file uploads, letting you verify how models process images or documents without configuring storage buckets or authentication separately.
Exporting configurations to production code
Studio generates ready-to-use code snippets in Python, Node.js, or Java once you finalize your prompt and parameters. You click the "Get Code" button to receive properly formatted API calls that include your exact settings, authentication patterns, and error handling logic. This export feature eliminates translation errors between your prototype and production implementation, ensuring your deployed application behaves identically to your Studio testing environment.
Mastering prompt design and model tuning
Your success with google vertex ai generative ai depends heavily on how well you craft prompts and configure model parameters to match your specific requirements. The platform provides multiple approaches to optimize model performance, from simple prompt engineering techniques to sophisticated fine-tuning workflows that adapt models to your domain. You gain better results by understanding how different instruction formats affect output quality and when to invest time in customization versus using pretrained capabilities. Testing systematically across these options helps you identify the most cost-effective path to your desired outcomes.
Crafting effective prompts
Prompt structure directly impacts the quality and consistency of responses you receive from generative models. You achieve better results by providing clear context, specific instructions, and examples of desired output format within each request. The platform responds more accurately when you break complex tasks into sequential steps rather than expecting models to handle multiple operations simultaneously.
Your prompts should include role definitions that frame how the model approaches tasks, such as "You are a technical documentation expert" for writing developer guides. You specify output constraints like length limits, formatting requirements, or tone preferences to reduce the iterations needed. Temperature and top-p parameters let you control randomness in responses, with lower values producing more deterministic outputs for tasks requiring consistency.
When you provide few-shot examples showing input-output pairs, models learn your preferred patterns faster than from instructions alone.
Fine-tuning models for specific tasks
Fine-tuning adapts pretrained models to your unique datasets and business requirements when prompt engineering alone doesn’t deliver sufficient accuracy. You upload labeled examples that demonstrate the exact behavior you want, and the platform adjusts model weights through additional training cycles. This process improves performance on specialized terminology, industry-specific formats, or proprietary knowledge that doesn’t exist in general training data.
Your fine-tuning dataset typically requires hundreds to thousands of examples depending on task complexity and desired quality improvements. The platform handles infrastructure provisioning automatically during the training process, monitoring progress and alerting you when the tuned model becomes available for deployment. You evaluate fine-tuned versions against base models using your own test cases to verify the performance gains justify additional costs, since custom models often carry higher per-token pricing than standard options.

Final thoughts on Vertex AI
Google vertex ai generative ai consolidates everything you need for enterprise AI development into a single platform that eliminates the complexity of managing multiple tools and providers. You get access to cutting-edge models like Gemini alongside open source alternatives, combined with infrastructure that scales automatically and security features that meet regulatory requirements. The platform reduces the time between concept and production deployment through Studio’s rapid prototyping capabilities and automated MLOps workflows that handle versioning, monitoring, and rollbacks without manual intervention.
Your path forward depends on starting with small experiments in Studio, testing different models against your specific use cases, and gradually building toward production-grade applications as you gain confidence with the platform. Success requires balancing prompt engineering with fine-tuning investments based on your performance requirements and budget constraints. If you’re exploring AI tools to enhance your projects and productivity, discover more AI innovations at ThinkZipper where we curate the latest solutions across various domains.


